

A new column in an upstream file shouldn’t make your executive dashboard disappear. Yet Delta Lake schema evolution can accept an upstream schema change that still breaks a Power BI refresh, a transformation, or a business metric.
The safest approach is to let ingestion adapt while keeping the reporting contract stable. That means choosing the right Delta write option, checking downstream dependencies, and releasing changes to semantic models deliberately. Start with the distinction between what a table can store and what a report expects.
Key Takeaways
- A successful Delta Lake write doesn’t guarantee that downstream transformations, semantic models, or Power BI refreshes will work. Treat adding a field to a table and approving it for enterprise reporting as separate decisions.
- Use
mergeSchemafor approved additive changes, such as a new source column. ReserveoverwriteSchemafor planned schema replacement, and review renames, drops, and type changes for compatibility. - Keep the reporting contract stable with landing and curated layers, owned semantic models, and dependency checks across pipelines, queries, and reports.
- Test data quality, transformations, semantic-model refreshes, and streaming recovery before release. Record table versions and plan recovery for both the Delta table and reporting model.
Where Delta Lake schema evolution stops protecting you
Delta Lake stores a table’s schema alongside its transaction history. Schema enforcement rejects writes that don’t match the target table, preventing unexpected input structures from slipping in. Schema evolution allows selected changes, such as adding a column, when you enable the appropriate behavior.
These controls apply at the table boundary. A successful write doesn’t prove that every downstream consumer still works. A Power Query step might expect a column name that has changed. A semantic model might rely on a data type or relationship that no longer behaves as intended.
A newly accepted field isn’t automatically a trusted KPI. Before publishing it for enterprise reporting, define the schema change, assign an owner, and add checks. The practical distinction is simple: accepting a field into a Delta table and publishing it for enterprise reporting are separate decisions.
Choose the Delta write option that matches the change
Microsoft Fabric’s Delta Lake guidance separates additive schema merging from schema replacement. Treat these as different operations, not interchangeable fixes for a schema mismatch. Choose the narrowest schema change that meets the business requirement.
| Change needed | Typical approach | Reporting risk |
|---|---|---|
| Add a new source column | Append with mergeSchema | Existing reports may keep working, but transformations still need testing |
| Replace the table’s schema | Overwrite with overwriteSchema | Removed or changed fields can break consumers |
| Rename, drop, or change a type | Plan a controlled table change | Dependencies and compatibility need review |
Add columns with mergeSchema
For a PySpark DataFrame, an append can use df.write.format("delta").mode("append").option("mergeSchema", "true").saveAsTable(target_table). This option allows incoming columns missing from the existing table to be added. Earlier rows have no values for those new fields.
Delta Lake schema evolution is useful when a source introduces an optional attribute. It doesn’t validate the attribute’s meaning, change existing column types, or remove old columns. Check the resulting schema and data before promoting the new field to a curated table. A Fabric Delta table schema walkthrough offers additional context on evolution and audit history.
Reserve overwriteSchema for planned replacement
Use overwriteSchema when you intend to replace the target schema through an overwrite operation. For example, .option("overwriteSchema", "true") makes the incoming DataFrame’s schema the table definition. It isn’t an append mode switch: append adds records to an existing table, while schema overwrite changes the table definition. A Spark Delta schema discussion illustrates why replacement needs different treatment from adding columns.
Treat a rename, drop, or type change as a schema change that requires a planned compatibility review, not just a write-option adjustment. Confirm how the table handles the operation, inspect every dependent query, and plan any rewrite or cleanup needed for old data. For type changes, check the platform’s supported widening behavior and table configuration rather than assuming every conversion is safe.
Keep the Power BI reporting contract stable
A Microsoft Fabric Lakehouse can serve as a governed data lake landing area for changing Delta data in OneLake. Raw data isn’t automatically business-ready, so add transformations and validation before tables or views reach reports.
Separate incoming fields from approved metrics
Three boundaries work well: a landing table that reflects the source, a curated layer with approved column names and types, and Fabric semantic models that define measures and relationships. A Microsoft Fabric Warehouse can provide a governed SQL-facing layer when reporting teams need one.
For example, if an order feed gains a new status field, the landing table can accept it first. Promote it to the curated Delta table only after the team agrees on its meaning and valid values. Review the schema change’s impact on existing measures first. The design of Fabric semantic models matters because several reports may share the same measure definitions.
This separation reduces the urge to repair every dashboard with a separate Excel export. It also makes Microsoft Fabric Power BI integration more dependable during analytics modernization.
Review the full dependency path
Before changing a reporting-facing table, trace its pipelines, notebooks, Dataflows Gen2, SQL queries, semantic models, and scheduled refreshes. Check dependencies by column, not just by table name.
Power BI semantic model optimization belongs in that review. Remove unused fields, verify relationships, and test measures against old and new records. If your organization uses Copilot in Power BI, curated model definitions and careful selection of exposed fields also affect the answers business users receive.
Plan for schema changes in streaming pipelines
Batch jobs can inspect a new file before the next scheduled write. With structured streaming, changes can disrupt a running query, so its failure and recovery path needs equal attention.
Expect a stream to need a restart
An upstream schema change can cause a running query to fail. A structured streaming query may need a restart and re-plan against the updated schema in Apache Spark. Don’t treat an automatic job retry as proof that the new field was processed correctly.
In Databricks, Auto Loader can detect a new column in incoming files, update the schema at its schema location, and stop with an UnknownFieldException. An orchestrator can restart the job after the team confirms the change is acceptable, using Auto Loader’s updated schema. Its additive schema handling doesn’t automatically change the types of existing columns.
Check every layer of the stream
For Kafka ingestion, separate the producer contract, serialized format, Spark processing schema, and target Delta table schema. A schema registry can govern producer messages, but it doesn’t approve changes to a Fabric reporting model.
If the pipeline also uses Fabric Real-Time Intelligence, review its downstream analytics separately. A field arriving in a stream still needs stable interpretation before it becomes a measure that operations teams use.
Test the change before reports depend on it
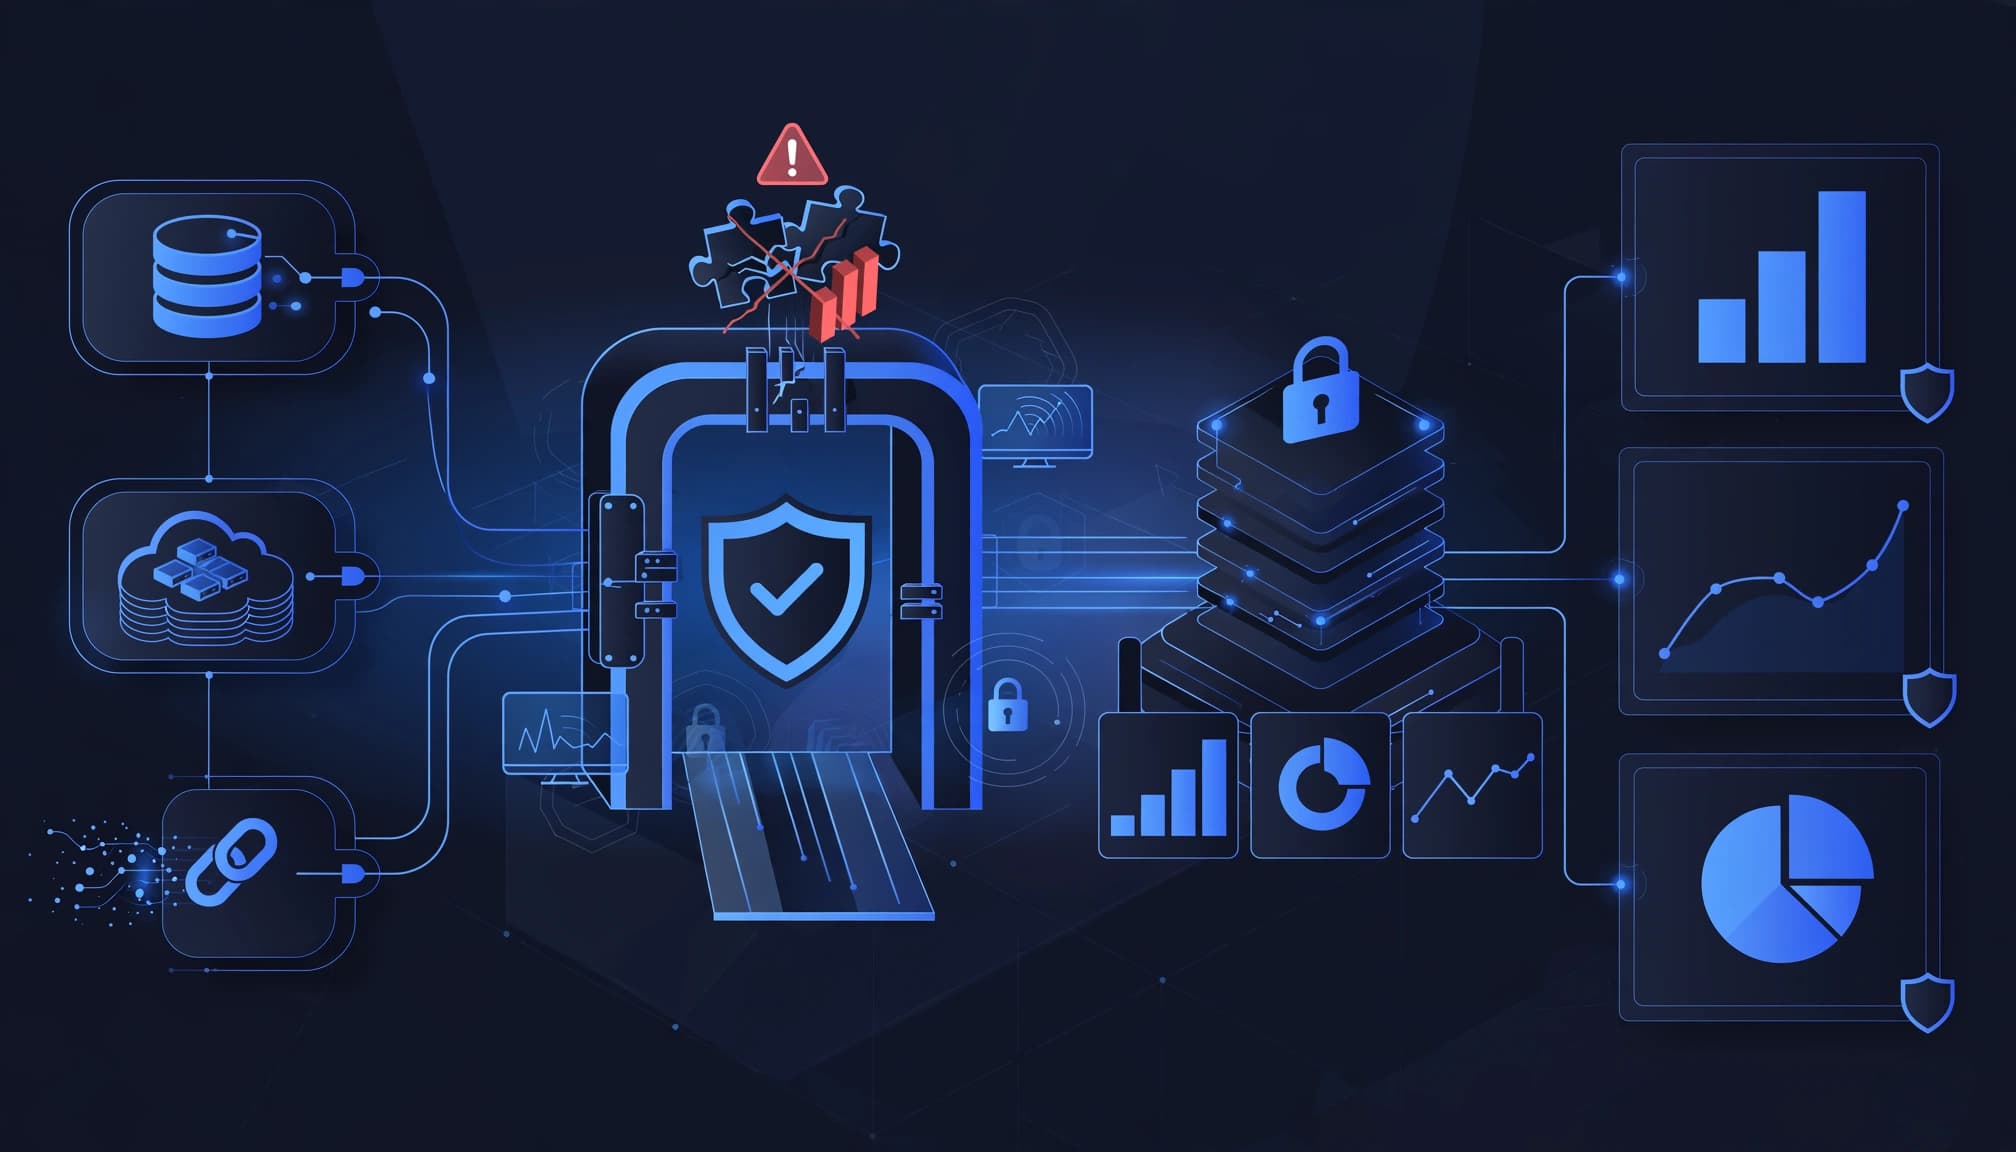
A production release needs evidence that the new schema works across the whole path, not only that a Delta write succeeds. Validate the schema change before deployment, and require an owner to approve changes to reporting-facing fields.
Validate data and dependencies together
At ingestion, use schema enforcement to check the incoming column’s name, type, null rate, and allowed values. Then compare row counts and key measures before and after the change. A newly added field can expose a data quality issue even when the original columns remain intact.
Next, run the affected transformations and refresh dependent semantic models in a nonproduction environment before promoting to the production environment. Test the reports people use to close the month or manage daily operations, as well as structured streaming restarts and newly processed records alongside batch refreshes. Spargent’s Microsoft Fabric governance guidance addresses the ownership and model oversight needed for that process.
Keep a recovery path
Record the Delta table version before a release. Delta time travel lets teams inspect historical table versions when investigating a change, subject to retained history and data files. It helps with diagnosis, but a historical query alone won’t repair a changed Power BI model.
For a failed release, know which pipeline can pause, which table or transformation must be restored, and who can approve a restart. Keep failed records available for inspection rather than repeatedly replaying an unverified schema.
A rollback plan must cover the reporting model as well as the table. Restoring table data won’t reverse a separately published semantic-model change.
Make schema changes part of Fabric migration planning
A move to Fabric is a good time to map reporting dependencies that legacy jobs never documented. Before you migrate to Microsoft Fabric, inventory source columns, transformations, refresh schedules, model owners, and reports tied to close or operational decisions. Include any schema change that could affect those dependencies.
For a Power BI to Microsoft Fabric migration, move a limited reporting domain first. Validate its curated Delta tables, semantic models, and structured streaming workloads while the existing reporting path remains available. Then expand ingestion through Fabric Data Factory pipelines or Dataflows Gen2, defining each data pipeline as its source contract becomes clear. Teams that need help with those choices can use Microsoft Fabric data engineering consulting to plan lakehouse, Spark, and pipeline work.
After go-live, monitor refresh failures and capacity use alongside schema alerts. Microsoft Fabric performance optimization and capacity planning matter when new fields increase transformation work or enlarge models. Data platform modernization pays off when reports arrive faster and need less manual repair, not when a migration simply moves the same fragile workflow.
Customer success: Tata Realty’s Fabric modernization
Microsoft’s customer story on Tata Realty and Infrastructure Ltd. reports a 20% to 30% reduction in annual analytics costs and a 20% reduction in data processing time after the company’s Microsoft Fabric modernization.
Those results aren’t attributed to schema evolution. They show the broader business outcome that a dependable data foundation should support: less time spent processing data and better control of analytics costs. Schema controls contribute by keeping source changes from turning into recurring reporting repairs.
Get specialist support without building a full team
U.S. mid-market and enterprise teams may have strong Power BI users or internal analytics teams, yet lack senior capacity for Delta pipelines, Fabric governance, and platform operations. Spargent Analytics is a Microsoft Fabric consulting and delivery partner for U.S. organizations, including those without a dedicated analytics engineering team.
Senior European Fabric specialists support ingestion, Data Factory pipelines, Dataflows Gen2, Lakehouse and Warehouse design, and OneLake. They also handle Power BI and semantic models, governance, optimization, and managed support. The EU-to-USA model combines strong U.S.-focused communication with an efficient cost structure, potentially improving ROI over staffing every specialist role locally.
If schema changes are slowing reports or complicating a Fabric rollout, Book a Microsoft Fabric Discovery Call to review the pipeline and identify reporting risks. Get a plan for safer changes, faster implementation, and less manual repair.
Frequently Asked Questions
What does Delta Lake schema evolution do?
Schema evolution allows selected schema changes, such as adding incoming columns, when the appropriate write behavior is enabled. It doesn’t verify that a new field is meaningful or that downstream reports can use it safely.
When should I use mergeSchema?
Use mergeSchema for an approved additive change, such as a new source column during an append. Check the resulting schema and data, and test dependent transformations before promoting the field for reporting.
When should I use overwriteSchema?
Use overwriteSchema when a planned overwrite is intended to replace the table’s schema with the incoming DataFrame’s schema. Because removed or changed fields can affect consumers, review dependencies and compatibility before release.
Can a schema change interrupt a streaming pipeline?
Yes. An upstream change can cause a structured streaming query to fail, and the query may need to restart and re-plan against the updated schema. Confirm the new field is acceptable and verify newly processed records rather than relying on an automatic retry.
How can I reduce the risk of breaking Power BI reports?
Trace dependencies from the Delta table through transformations and queries to semantic models and scheduled refreshes. Validate the change in a nonproduction environment, test affected reports, and keep a recovery plan that covers the reporting model as well as the table.
Conclusion: evolve the table, protect the report
The new column that reaches a Delta table safely can still disrupt a dashboard. Keep schema enforcement at ingestion, use evolution only for approved changes, and publish reporting fields through tested, owned models.
That boundary lets data teams accommodate upstream change without asking business users to question every refreshed number.
